Projects
Things I've built end to end — each one links out to the code, a write-up, or a deeper page.
LLM Serving Stack
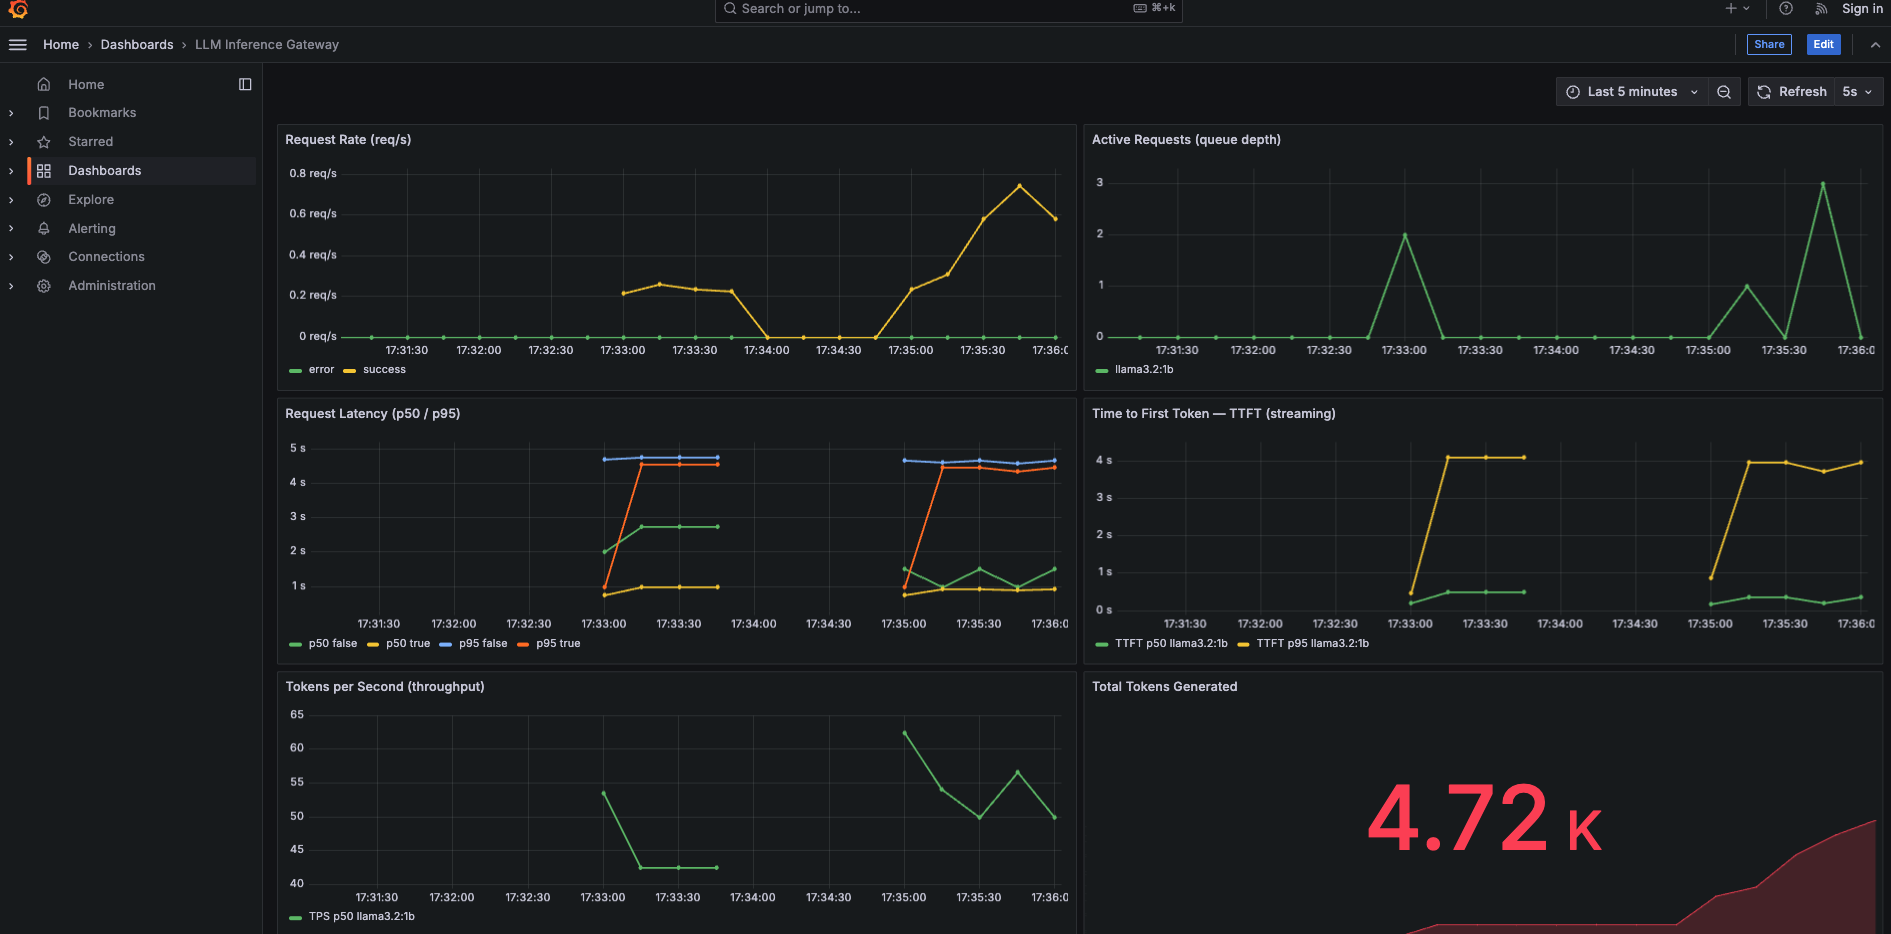
An OpenAI-compatible inference gateway in front of Ollama: admission control, streaming, prompt-based routing, auth and rate limiting, with Prometheus, Grafana and Jaeger behind it. It speaks the protocol vLLM and TGI use; a real vLLM has not yet run behind it.
- 1 · Rebuilding the layer around vLLM, on a laptop with no GPU: a queue is admission control, not batching
- 2 · Routing across local and cloud backends (in progress)
Gurukul: A robot learning stack on a real arm
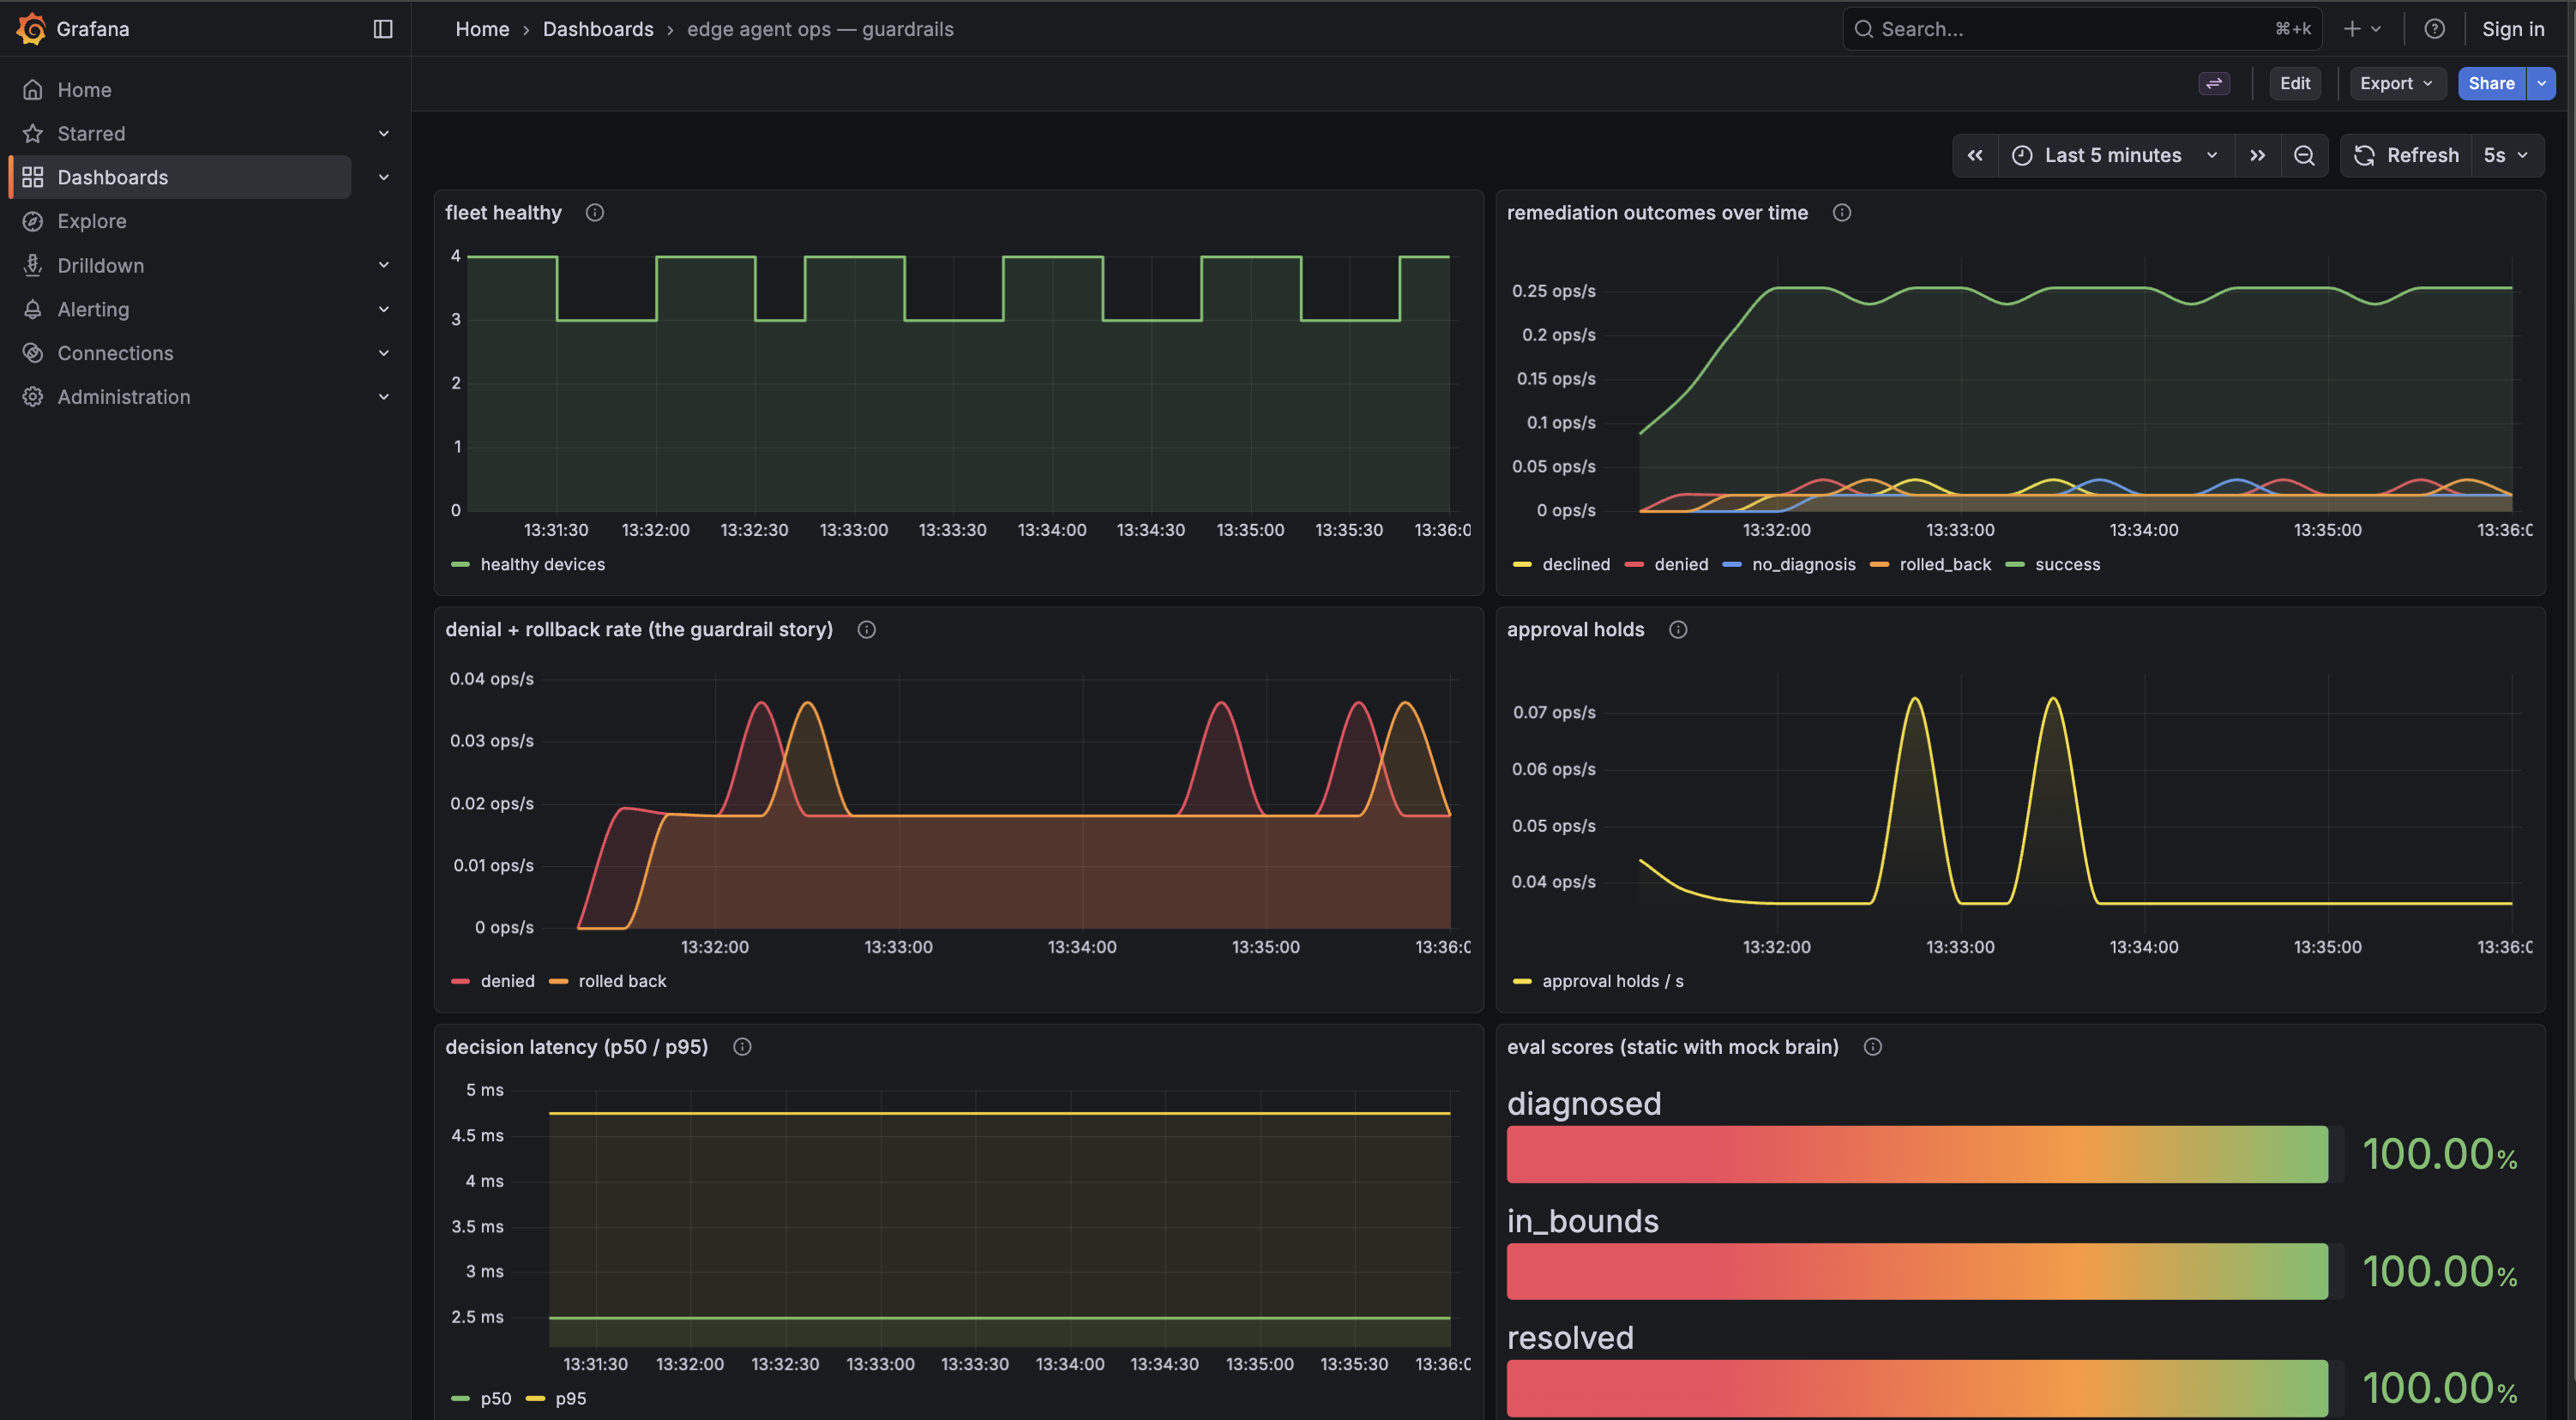
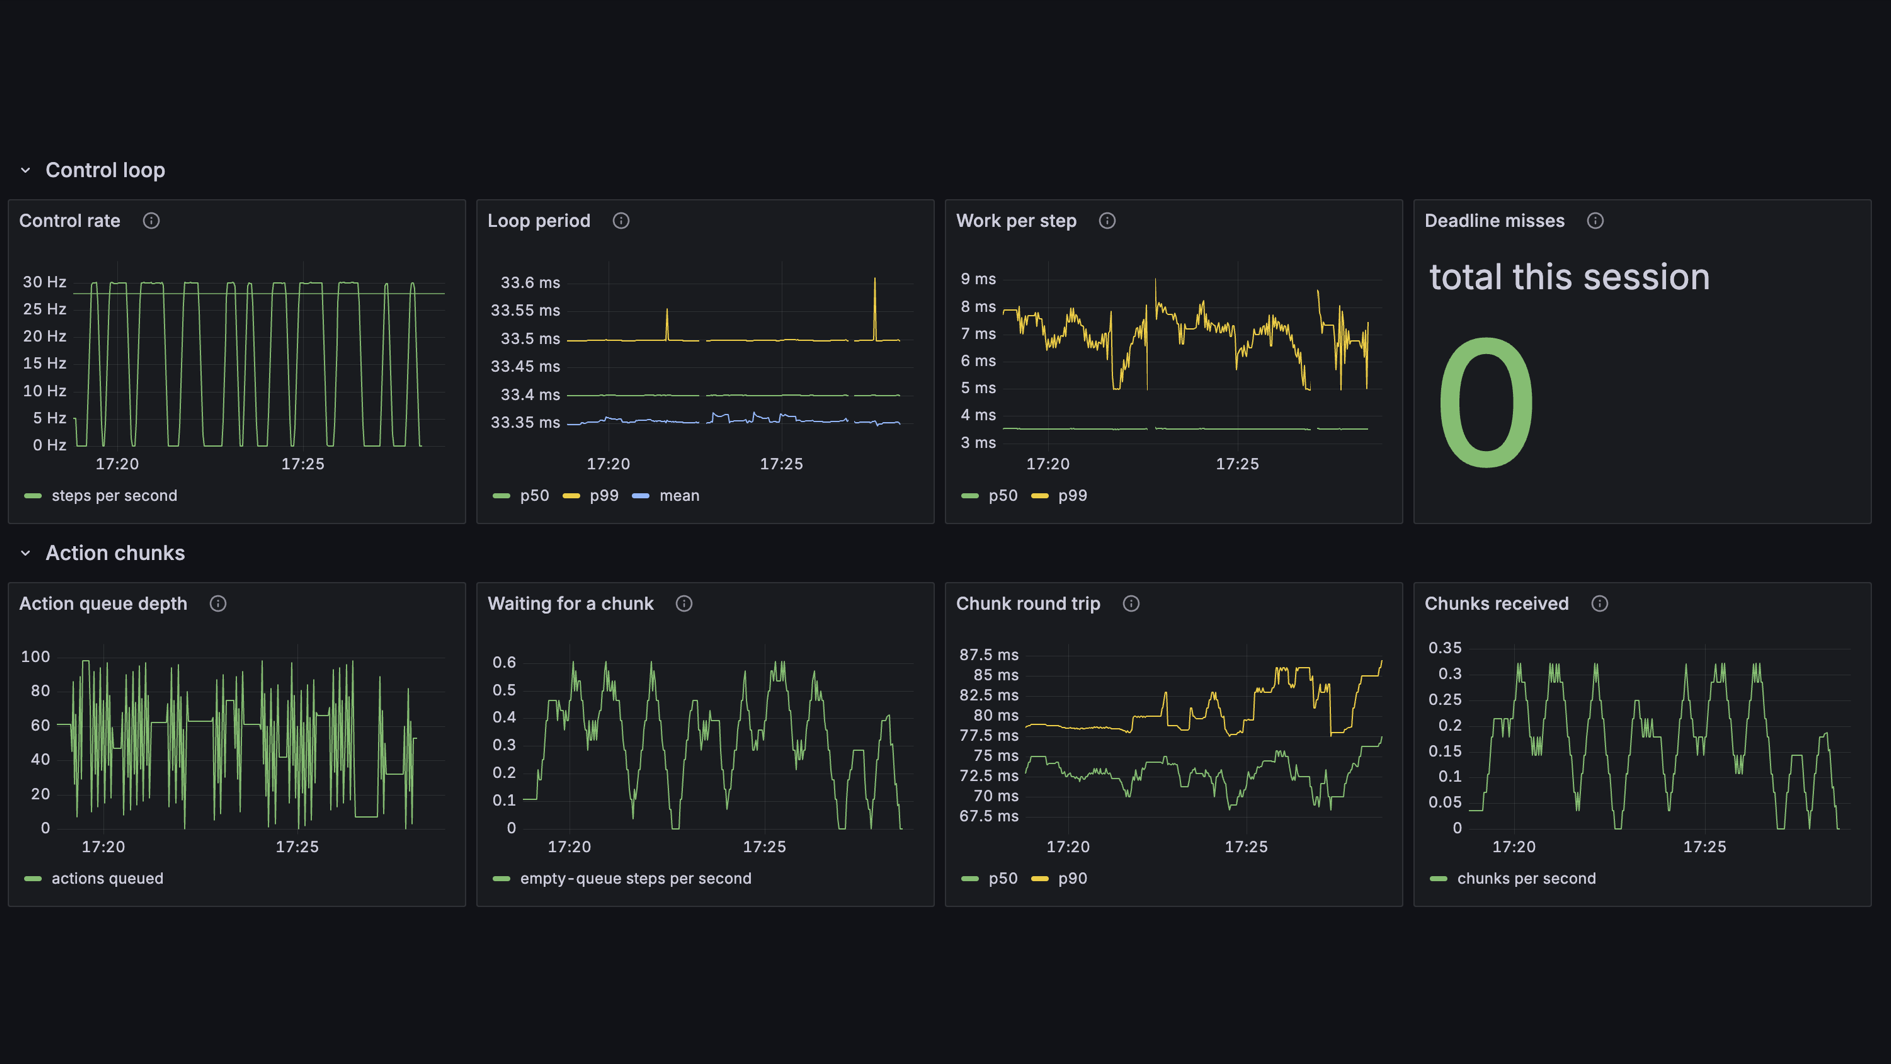
One low-cost SO-ARM101 arm, built up one project at a time with Hugging Face LeRobot: imitation learning, serving and observability, and data curation at scale.
- 1 · Imitation learning from scratch: an ACT policy, 10/20 on the real arm
- 2 · Serving and observability: gRPC, Prometheus, Grafana, a slow server on purpose; 9/20 served
- 3 · Curating public data with Ray: 78,000 episodes scored, 15/20 curated against 8/20 random
- 4 · A pretrained vision-language-action model on the same task (planned)
Ray Multimodal Pipeline
A distributed multimodal pipeline on Ray that ingests autonomous-driving sensor data (camera + lidar + metadata), preprocesses it, and runs pretrained-model batch inference at scale — writing structured Parquet. An exercise in ML-infra orchestration: stateless Ray Data tasks for preprocessing, an actor pool for inference.